
Data Classification for AI
Last updated on 2026-08-27 | Edit this page
Estimated time: 20 minutes
Overview
Questions
- How do you classify data for AI tool usage?
- What is the difference between PUBLIC, PROPRIETARY, and RESTRICTED data?
- Which AI tools are appropriate for each classification?
Objectives
- Classify research data into the three Pomona tiers
- Map data classifications to appropriate AI tools
- Apply the data classification decision tree
- Document data handling for audit trails
The Three Tiers
Tier 1: PUBLIC
Information that is already public or could be made public without harm.
Examples: Published research papers, public datasets (Kaggle, UCI ML Repository), conference presentations, general knowledge, anonymous aggregated statistics.
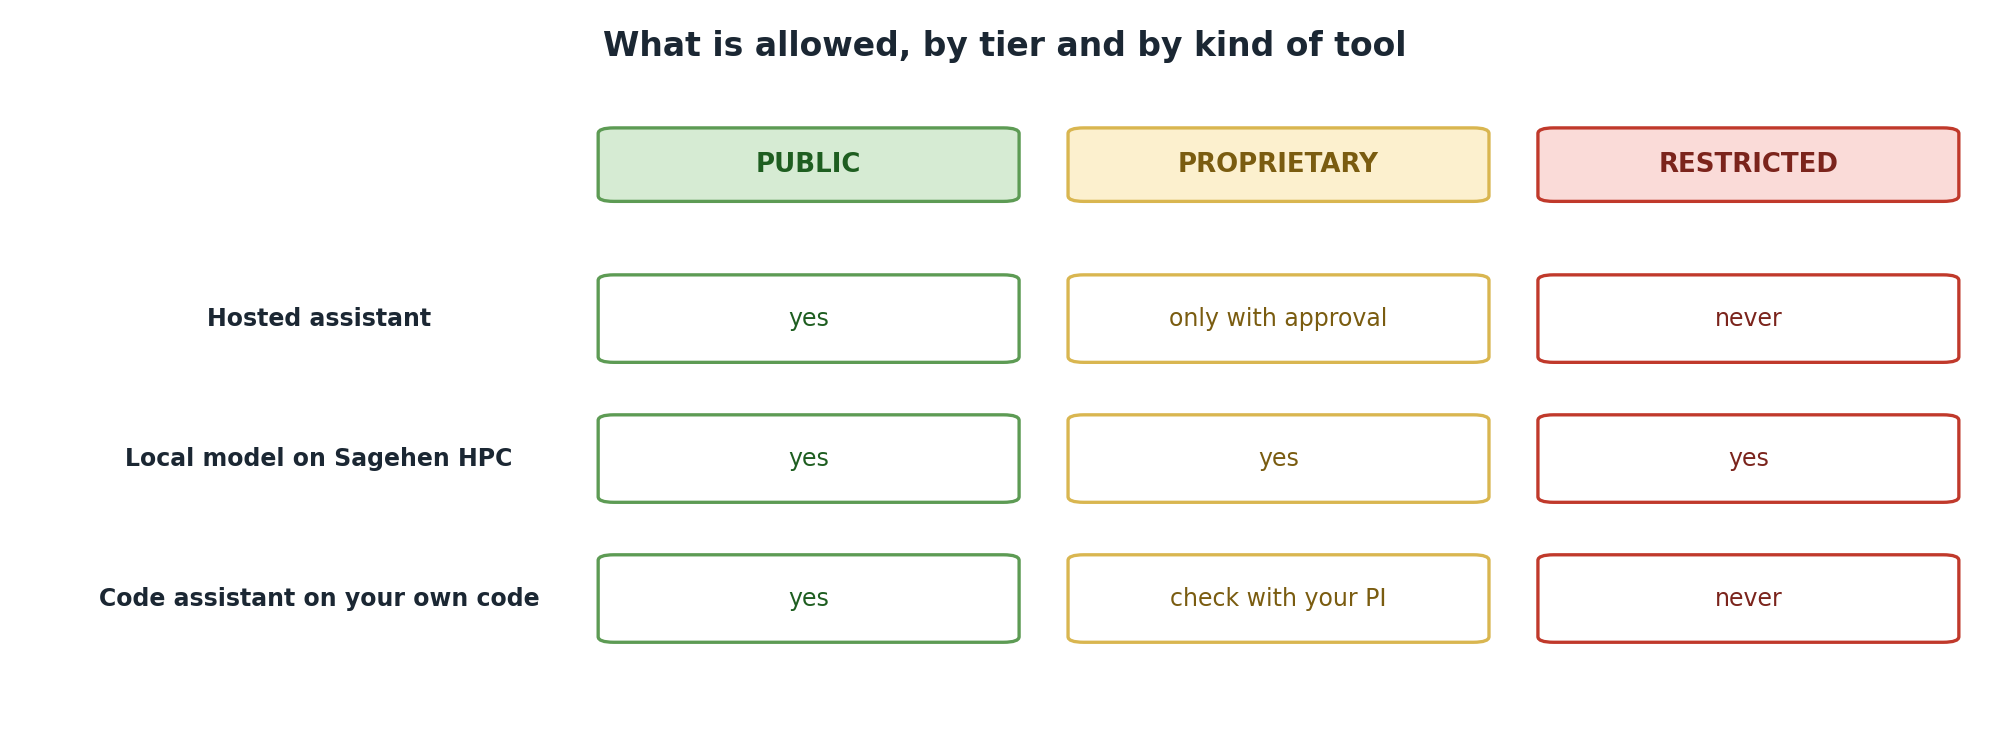
AI Tool Policy: May use external AI (ChatGPT, Claude, Gemini, etc.)
Tier 2: PROPRIETARY
Information restricted to specific individuals or organizations.
Examples: Draft research (unpublished), lab notebooks, preliminary results, patent applications, NDA-covered research, proprietary algorithms, grant-funded research with restrictions.
AI Tool Policy: MUST use local AI only (Sagehen HPC GPUs). External AI requires explicit written permission from all stakeholders. Encryption recommended.
Tier 3: RESTRICTED
Highly sensitive information protected by federal law.
Examples: FERPA (student records, grades, IDs), medical/HIPAA data, financial records, export-controlled research (ITAR/EAR), PII (SSN, phone numbers, addresses), biometric data.
AI Tool Policy: LOCAL AI ONLY with mandatory AES-256-GCM encryption. No exceptions.
When in Doubt, Classify as RESTRICTED
If you are unsure about classification, default to RESTRICTED. You can always relax to a lower classification after confirming with your PI, IRB, or the privacy office.
Decision Tree for AI Tool Selection
1. Is the data already publicly available?
   YES -> External AI is acceptable
   NO  -> Continue

2. Does it contain FERPA, HIPAA, financial, or export-controlled data?
   YES -> LOCAL AI ONLY (Sagehen GPU) with encryption
   NO  -> Continue

3. Does it contain NDA, patent, or proprietary methods?
   YES -> LOCAL AI ONLY
   NO  -> Continue

4. Would sharing cause institutional embarrassment?
   YES -> Consider local AI (safer)
   NO  -> External AI is acceptable
Real-World Classification Examples
Student course evaluations: RESTRICTED (FERPA). Use a local model on Sagehen.
CSV with columns [ID, Age, Income, Disease_Status]: Could be RESTRICTED if ID is a real student ID. Remove the ID column to create a PUBLIC version.
Published research papers: PUBLIC. Safe with any AI tool.
Aggregated enrollment statistics (no individuals): PROPRIETARY. Use local AI or obtain written permission.
Safe Data Sharing Pattern
If you must use external AI with potentially sensitive data:
PYTHON
# STEP 1: Redact sensitive information
original = "Student Alice (ID: 12345) scored 92 on exam"
safe = "Student (ID: XXXXX) scored 92 on exam"

# STEP 2: Use external AI on redacted version only

# STEP 3: Apply results to original data locallyChallenge: Classify Your Data
For each scenario, classify the data and recommend AI tools:
- A list of 1000 student names and their major
- Published research paper about climate change
- Your lab’s unpublished results with no identifiers
- Code from a public GitHub repository
- Export-controlled research paper (marked CONTROLLED)
- Student names + major: RESTRICTED (FERPA). Local AI only on Sagehen.
- Published climate paper: PUBLIC. External AI safe.
- Lab results, anonymized: PROPRIETARY. Local AI preferred; external with written permission.
- Public GitHub code: PUBLIC. External AI safe.
- Export-controlled: RESTRICTED. Local AI only, with encryption.
The data classification – not the AI tool capability – determines your choice.
- PUBLIC data: safe with external AI tools
- PROPRIETARY data: local AI only, or external with explicit written permission
- RESTRICTED data (FERPA, medical, financial, export-controlled): never external AI
- Use the decision tree to classify before selecting any AI tool
- Redact personal identifiers before sharing data with any external tool