
SLURM Scripts for ML
Last updated on 2026-08-24 | Edit this page
Overview
Questions
- How do you write SLURM scripts for GPU training jobs?
- How do you request GPU resources correctly?
- How do you launch multi-GPU training with SLURM?
Objectives
- Write SLURM batch scripts for GPU training
- Request appropriate GPU, CPU, and memory resources
- Launch distributed training with torchrun and SLURM
Single-GPU SLURM Job
BASH
#!/bin/bash
#SBATCH --job-name=pytorch_training
#SBATCH --partition=gpu
#SBATCH --gres=gpu:1
#SBATCH --cpus-per-task=4
#SBATCH --mem=16GB
#SBATCH --time=02:00:00
#SBATCH --output=training_%j.log

module load miniconda3/py313_26.3.2-2   # then activate your conda env -- no pytorch module exists

python3 << 'EOF'
import torch
print(f"GPU available: {torch.cuda.is_available()}")
print(f"GPU device: {torch.cuda.get_device_name(0)}")

# Your training code here
EOF
Submit and monitor:
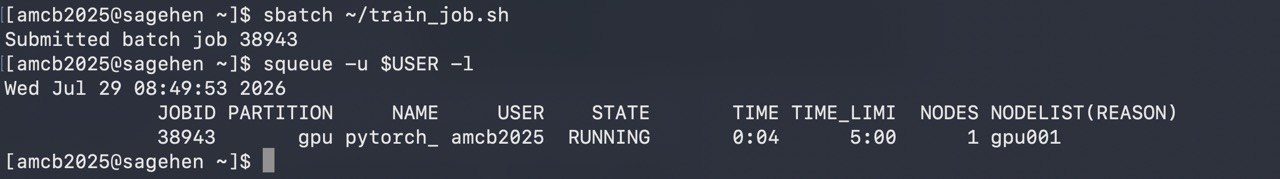
Submitting the training job and confirming with
squeue -l that it’s RUNNING on a GPU node.TensorFlow SLURM Job
BASH
#!/bin/bash
#SBATCH --job-name=tf_training
#SBATCH --partition=gpu
#SBATCH --gres=gpu:1
#SBATCH --cpus-per-task=4
#SBATCH --mem=32GB
#SBATCH --time=04:00:00
#SBATCH --output=tf_training_%j.log

module load miniconda3/py313_26.3.2-2   # then activate your conda env -- no tensorflow module exists

python3 << 'EOF'
import tensorflow as tf
gpus = tf.config.list_physical_devices('GPU')
for gpu in gpus:
    tf.config.experimental.set_memory_growth(gpu, True)

# Your TensorFlow training code here
EOF
Multi-GPU SLURM Job
BASH
#!/bin/bash
#SBATCH --job-name=multi_gpu_training
#SBATCH --partition=gpu
#SBATCH --gres=gpu:4
#SBATCH --cpus-per-task=16
#SBATCH --mem=64GB
#SBATCH --time=04:00:00
#SBATCH --output=training_%j.log

module load miniconda3/py313_26.3.2-2   # then activate your conda env -- no pytorch module exists

# Set master node details for distributed training
export MASTER_ADDR=$(scontrol show hostname ${SLURM_NODELIST} | head -n1)
export MASTER_PORT=29500
export WORLD_SIZE=$SLURM_GPUS_PER_NODE

# Launch with torchrun (automatic launcher)
torchrun --nproc_per_node=4 train_distributed.py
Interactive GPU Sessions
OnDemand Web Interface
Access via https://ondemand.hpc.pomona.edu:
- Log in with Pomona credentials
- Click “Jupyter Lab” or “Terminal”
- Select GPU and duration
- Upload your code
Resource Guidelines
| Workload | GPUs | CPUs | Memory | Time |
|---|---|---|---|---|
| Quick test | 1 | 4 | 16 GB | 30 min |
| Single-GPU training | 1 | 4 | 16-32 GB | 2-8 hours |
| Multi-GPU training | 4 | 16 | 64 GB | 4-24 hours |
| Hyperparameter sweep | 1 per job | 4 | 16 GB | 2 hours each |
Challenge
Challenge: Write a Training Job Script
Write a SLURM script that requests 1 GPU, loads your conda environment, copies data from /bigdata to /scratch, runs training, and saves the model back to /bigdata.
BASH
#!/bin/bash
#SBATCH --job-name=my_training
#SBATCH --partition=gpu
#SBATCH --gres=gpu:1
#SBATCH --cpus-per-task=4
#SBATCH --mem=16GB
#SBATCH --time=04:00:00
#SBATCH --output=training_%j.log

module load miniconda3
conda activate pytorch_env

# Copy data to fast storage
cp -r /bigdata/lab/<labname>/dataset /scratch/$USER/dataset

# Run training
python3 train.py --data /scratch/$USER/dataset --output /scratch/$USER/model.pt

# Save results back to persistent storage
cp /scratch/$USER/model.pt /bigdata/lab/<labname>/models/Important: Always Test First
Before submitting a large GPU job: 1. Run on CPU with small dataset (10 iterations) 2. Check GPU memory usage with an interactive session 3. Verify checkpointing works 4. Then scale up to full training
- Use
--partition=gpuand--gres=gpu:Nto request GPU resources - Request 4 CPUs per GPU as a rule of thumb
- Use torchrun for launching distributed PyTorch training
- Test interactively with
srunbefore submitting batch jobs - Copy data to /scratch for faster I/O during training