
MPI Basics
Last updated on 2026-08-27 | Edit this page
Overview
Questions
- How do I write and run MPI programs in Python?
- How do I distribute data across ranks?
- What are common MPI patterns?
- When is MPI worth the complexity over simpler approaches?
Objectives
- Write MPI programs using mpi4py
- Distribute and gather data across MPI ranks
- Implement parallel integration with MPI
- Decide when MPI is the right tool
What MPI Is and Why It Exists
MPI (Message Passing Interface) is the standard for cross-node parallelism in HPC. Where shared-memory parallelism (multiprocessing, OpenMP) works on one node and SLURM job arrays work for embarrassingly parallel jobs that need no coordination, MPI handles the case in the middle: many processes on many nodes that need to talk to each other while computing.
MPI’s model is rigid but powerful. You launch N processes (called
ranks) at the same time. Each rank knows its own ID (rank)
and the total count (size). Ranks coordinate through
explicit message-passing primitives: send, receive, scatter, gather,
broadcast, reduce. Memory is not shared; everything moves through
messages.
For 90% of research workflows, MPI is overkill. Job arrays are simpler and scale just as well. But for tightly-coupled simulations (climate models, molecular dynamics, distributed deep learning), MPI is essentially mandatory.
Hello World with mpi4py
PYTHON
#!/usr/bin/env python3
from mpi4py import MPI

comm = MPI.COMM_WORLD
rank = comm.Get_rank()
size = comm.Get_size()

print(f"Hello from rank {rank} of {size}")

comm.Barrier()

if rank == 0:
    print("All processes have said hello!")
Three concepts in this snippet form the core of MPI:
comm (the communicator, a group of processes that can
talk), rank (this process’s ID within the communicator),
and size (total number of processes).
comm.Barrier() is a synchronization point: every rank waits
until all ranks have reached it. Use it sparingly; barriers force
synchronization that throws away parallelism.
Run with SLURM:
BASH
#!/bin/bash
#SBATCH --ntasks=4
#SBATCH --cpus-per-task=1
#SBATCH --mem-per-cpu=1G
#SBATCH --time=00:05:00

srun python3 hello_mpi.py
The key SLURM directive is --ntasks=4, which tells SLURM
to launch 4 MPI processes. Use srun (not
mpirun) to launch on Sagehen HPC because srun
knows about SLURM’s allocation and places ranks correctly across
nodes.
Distributed Sum
PYTHON
#!/usr/bin/env python3
from mpi4py import MPI
import numpy as np

comm = MPI.COMM_WORLD
rank = comm.Get_rank()
size = comm.Get_size()

if rank == 0:
    data = np.arange(1, 101)
else:
    data = None

# Scatter data to all ranks
local_data = comm.scatter(np.array_split(data, size) if rank == 0 else None, root=0)
print(f"Rank {rank} received: {local_data}")

# Each rank computes partial sum
partial_sum = np.sum(local_data)

# Gather results at rank 0
total_sum = comm.reduce(partial_sum, op=MPI.SUM, root=0)

if rank == 0:
    print(f"Total sum: {total_sum}")
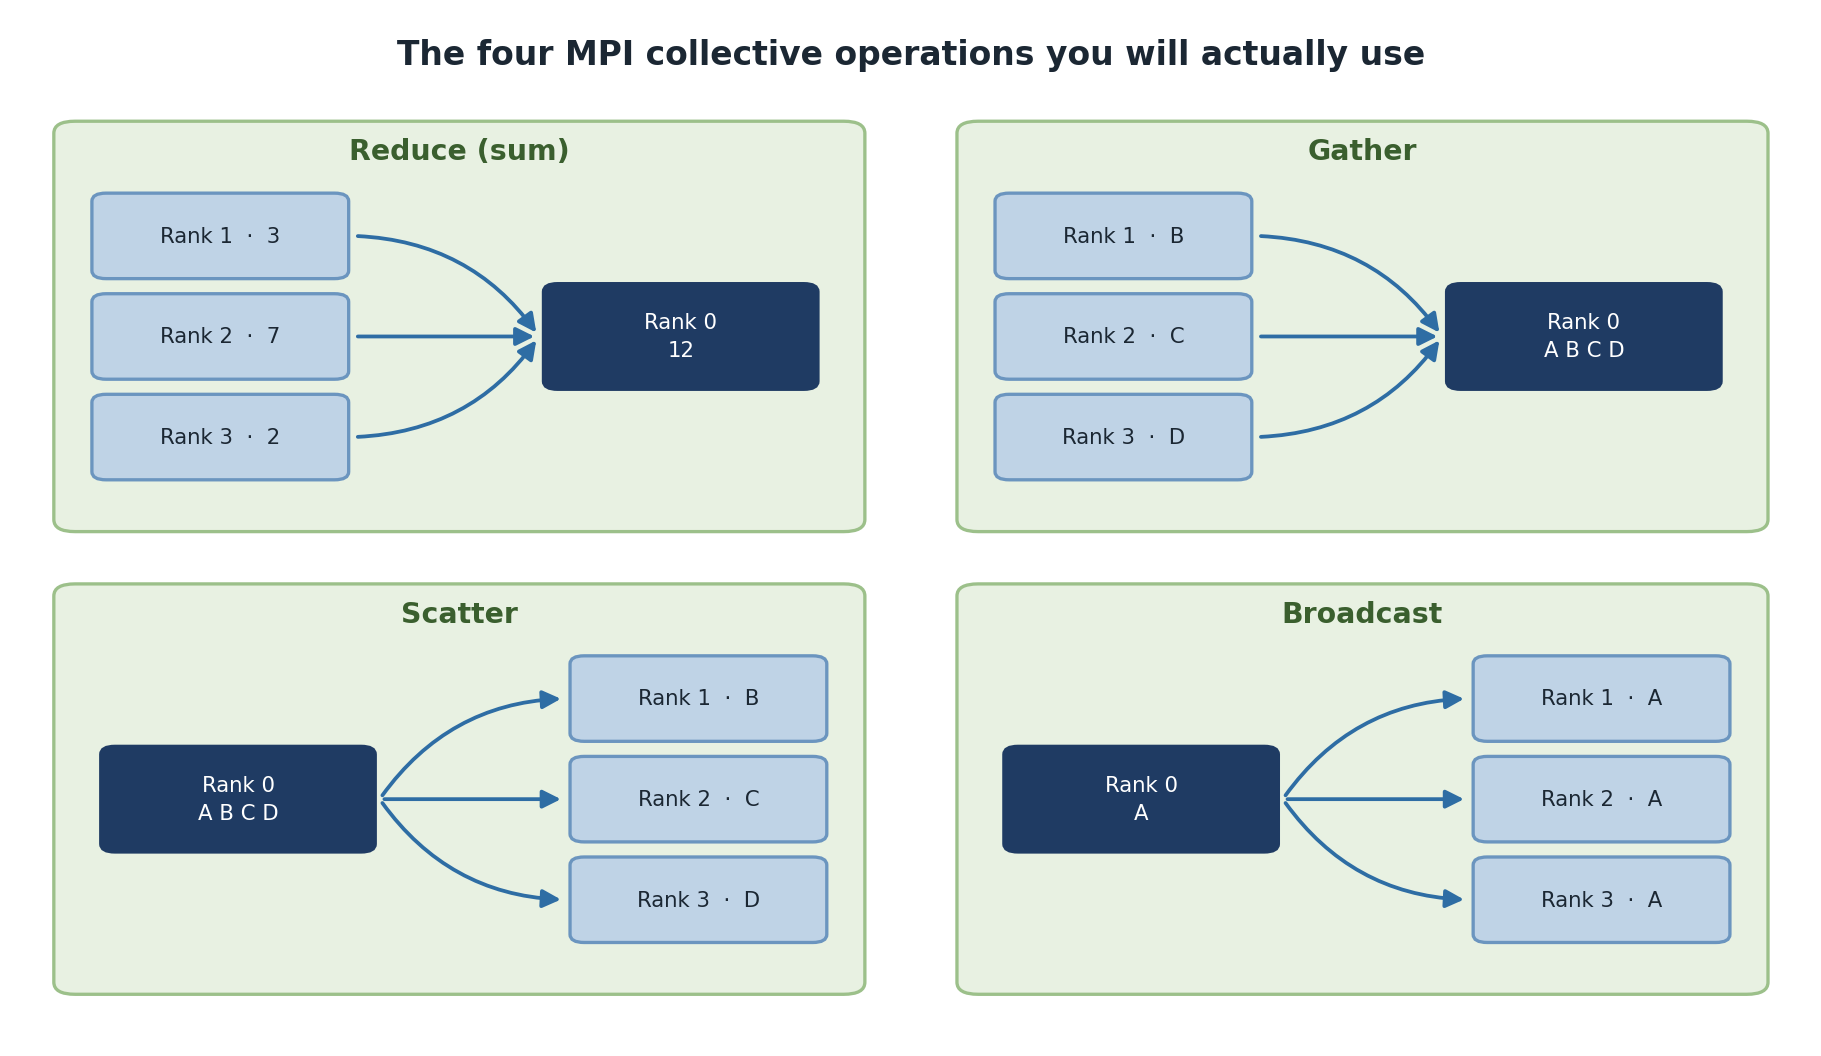
This shows the basic distribute-compute-collect pattern.
scatter splits an array on rank 0 into pieces and sends one
piece to each rank. Each rank computes locally. reduce
collects partial results back, applying an operation
(MPI.SUM, MPI.MAX, MPI.MIN, etc.)
along the way and depositing the result on rank 0.
comm.scatter and comm.reduce are the most
common collective operations. Other essentials:
-
comm.bcast(value, root=0): send the same value from rank 0 to every other rank. -
comm.gather(local, root=0): collect each rank’s local value into a list on rank 0 (no reduction). -
comm.allreduce(value, op=MPI.SUM): reduction whose result is delivered to every rank.
Parallel Integration
Compute an integral by having each rank calculate a portion:
PYTHON
#!/usr/bin/env python3
from mpi4py import MPI
import numpy as np

def integrate_range(a, b, n_steps):
    dx = (b - a) / n_steps
    x = np.linspace(a + dx/2, b - dx/2, n_steps)
    return np.sum(np.sin(x)) * dx

comm = MPI.COMM_WORLD
rank = comm.Get_rank()
size = comm.Get_size()

a, b = 0, np.pi
n_steps = 1_000_000

# Divide range across ranks
local_a = a + rank * (b - a) / size
local_b = a + (rank + 1) * (b - a) / size

local_integral = integrate_range(local_a, local_b, n_steps // size)
print(f"Rank {rank}: integral from {local_a:.3f} to {local_b:.3f} = {local_integral:.6f}")

total_integral = comm.reduce(local_integral, op=MPI.SUM, root=0)

if rank == 0:
    print(f"Total integral: {total_integral:.6f}")
    print(f"Expected: 2.0")
This is a classic MPI pattern: each rank gets disjoint work derived from its rank ID, computes locally, and contributes to a final reduction. There is no inter-rank communication during the actual computation, only at the end. This minimizes communication and gives near-linear scaling.
MPI Performance Considerations
MPI scales well only if:
- Computation >> Communication: Each rank does more work than it spends sending messages.
- Communication is infrequent: Not synchronizing every step.
- Messages are large: Amortize the per-message latency.
Two terms you will encounter:
Strong scaling: same problem size, more ranks. Speed-up is bounded by the serial fraction (Amdahl’s law) and by communication overhead. Strong scaling typically plateaus at 4 to 32 ranks.
Weak scaling: grow problem size proportionally with ranks. Each rank’s local work stays constant, only communication grows. Weak scaling is what you want for “I have 16x more data and 16x more ranks; should still take the same time”.
MPI is Complex, Use Only When Necessary
Possible issues: deadlocks (two ranks both waiting to receive from each other), unbalanced load (one rank has 10x more work and the others wait), message ordering bugs, MPI process-leak after a crash.
Before writing MPI code, ask: Can I solve this with job arrays or multiprocessing?
If the problem is embarrassingly parallel (no inter-rank communication needed): job arrays.
If the work fits on one node: multiprocessing.
If neither, and the data dependencies are tightly coupled: MPI.
For data-parallel deep learning specifically, prefer PyTorch’s
DistributedDataParallel or TensorFlow’s
MultiWorkerMirroredStrategy over raw MPI. They use MPI
under the hood (or NCCL) but expose a more friendly Python API.
Common MPI Pitfalls
Forgetting to launch with srun. Running
python script.py instead of
srun python script.py runs only one rank, with
size = 1. The script appears to work but is serial.
Mismatched send/receive. comm.send(data, dest=2)
requires a corresponding comm.recv(source=ANY) on rank 2 to
retrieve it. If the receive is missing, the sender hangs forever waiting
for the buffer to clear.
Using comm.send (point-to-point) when a collective
(scatter, gather, bcast) would
do. Collectives are optimized for the underlying network topology and
almost always faster than equivalent point-to-point patterns.
Heavy reliance on comm.Barrier(). Barriers force
synchronization across all ranks. Each barrier is a place where the
slowest rank holds up everyone else. Use them only where correctness
requires.
Challenge
Run an MPI Program
Write an MPI program where each rank computes the sum of a local
array segment, then all ranks contribute to a global sum using
comm.reduce.
PYTHON
from mpi4py import MPI
import numpy as np

comm = MPI.COMM_WORLD
rank = comm.Get_rank()
size = comm.Get_size()

local_sum = sum(i % 7 for i in range(10_000_000))
print(f"Rank {rank}/{size}: local sum = {local_sum}")

global_sum = comm.reduce(local_sum, op=MPI.SUM, root=0)
if rank == 0:
print(f"Global sum: {global_sum}, Average: {global_sum / size}")Challenge
Debug a Stalled MPI Job
A colleague’s MPI job runs for the full time limit and then gets killed. They see “Rank 0 sent message” in the log but no other output. List two likely causes and what to check.
Cause 1: rank 0 called comm.send(data, dest=1) but rank
1 never called the matching comm.recv. The send blocks
because the buffer is full. Verify: search the source for
send calls and check that each has a matching
recv on the destination rank.
Cause 2: rank 0 called a collective (bcast,
scatter, reduce) but only some ranks reached
the same call. Collectives require all ranks in the communicator to
participate. Verify: look for branching code (if rank == 0)
that calls a collective inside one branch only.
Both lead to deadlocks where the program runs forever. Adding
explicit print statements with flush=True
after each MPI call helps locate the offending line.
- mpi4py provides Python bindings for MPI
- Each rank knows its own ID (rank) and total count (size)
- scatter distributes data, reduce combines results
- Use srun (not mpirun) on Sagehen to launch MPI jobs correctly
- Each rank works on its portion independently, then results are gathered
- Strong scaling has limits (Amdahl’s law); weak scaling is more achievable
- MPI is powerful but complex; reserve for truly distributed problems
- For deep learning, prefer DistributedDataParallel over raw MPI