
Embarrassingly Parallel Problems
Last updated on 2026-08-27 | Edit this page
Estimated time: 20 minutes
Overview
Questions
- How do I know if my problem is embarrassingly parallel?
- What are common embarrassingly parallel patterns?
- How do I convert serial code to run in parallel?
Objectives
- Recognize embarrassingly parallel problems in your research
- Understand common patterns: parameter sweeps, Monte Carlo, batch processing
- Practice converting serial code to parallel structure
What Makes a Problem Embarrassingly Parallel?
A problem is embarrassingly parallel when:
- Tasks are completely independent: No communication between tasks
- Results don’t depend on task order: Task A doesn’t wait for Task B
- Each task needs only its input data: No shared state
- Results can be combined trivially: Simple aggregation at the end
Checklist: Is Your Problem Embarrassingly Parallel?
- Can each task run without data from other tasks? (YES = good)
- Does the order of execution matter? (NO = good)
- Can you run each task in isolation? (YES = good)
- Is combining results as simple as concatenating or averaging? (YES = very good)
If you answered YES to all four, use job arrays!
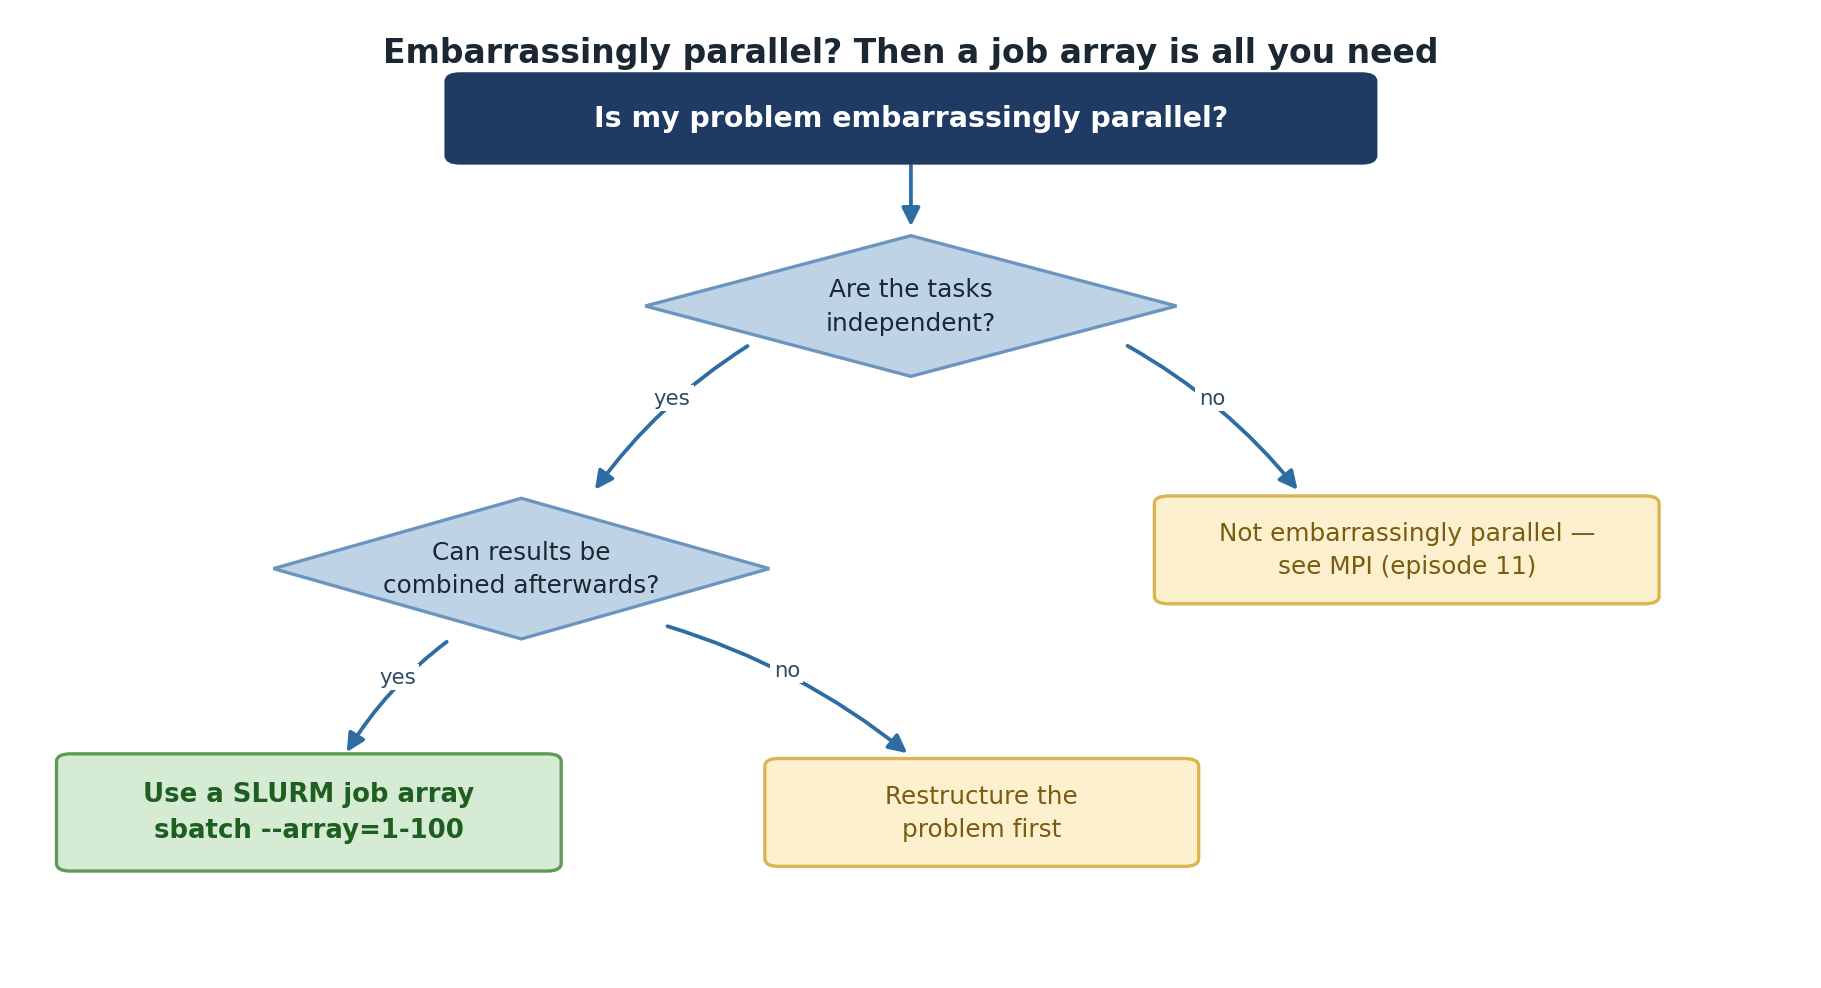
If the tasks are independent and the results can
be combined afterwards, a job array is all you need.
Common Patterns
Pattern 1: Parameter Sweeps
Serial: 100 learning rates x 30 seconds each = 50 minutes
Parallel (100 cores): 30 seconds
Pattern 2: Monte Carlo Simulations
PYTHON
def estimate_pi(n_samples, seed):
    random.seed(seed)
    inside = sum(1 for _ in range(n_samples)
                 if random.random()**2 + random.random()**2 <= 1)
    return 4 * inside / n_samples
Each random trial is independent. Run 100 jobs, average the results.
Converting Serial Code to Parallel
Step 4: Combine Results
Challenge
Is It Embarrassingly Parallel?
Code A: Analyze 1000 gene sequences independently:
Code B: Simulate a time series where each step depends on the previous:
Code A: YES. Each sequence is independent. Use job arrays for up to 1000x speedup.
Code B: NO. Each step depends on the previous one.
Look for other parallelism (e.g., parallelize within
evolve(), or run many independent simulations with
different initial conditions).
- Embarrassingly parallel problems have no dependencies between tasks
- Common patterns: parameter sweeps, Monte Carlo, batch processing, resampling
- Convert serial code by accepting parameters and using unique output files
- These are the easiest to parallelize and often the most valuable