
Choosing the Right Approach
Last updated on 2026-08-27 | Edit this page
Estimated time: 25 minutes
Overview
Questions
- How do I know which parallelization technique to use?
- How do I measure if parallelization is helping?
- What is the simplest approach that will work?
Objectives
- Follow a decision framework for parallelization
- Profile code and benchmark parallel performance
- Avoid common parallelization mistakes
Decision Framework
Measure Before You Optimize
NEVER parallelize code you haven’t profiled. You might optimize the wrong part or add complexity for minimal benefit.
PYTHON
import cProfile, pstats
cProfile.run('my_function()', 'profile_stats')
pstats.Stats('profile_stats').sort_stats('cumulative').print_stats(10)
Only parallelize if: computation takes minutes+, parallelizable fraction > 80%, and multiple cores are available.
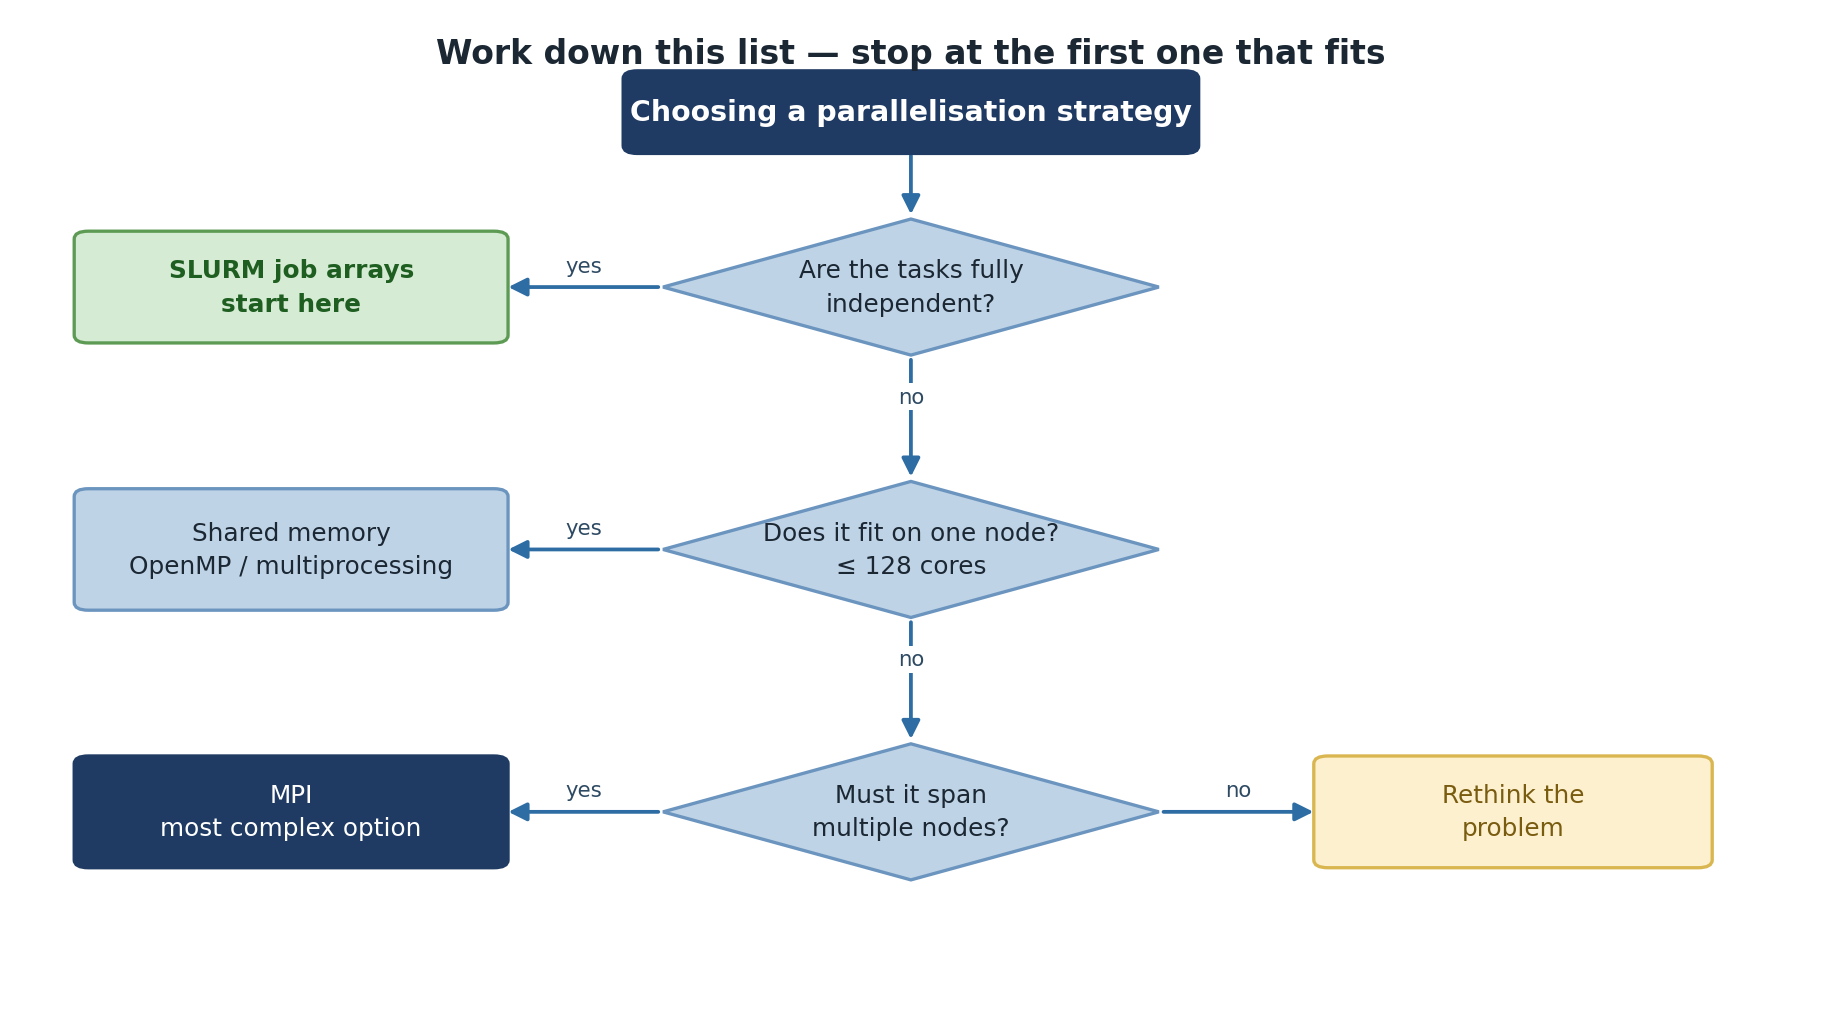
Decision Tree
Does it take > 1 minute?
  NO  -> Don't parallelize
  YES -> Is the parallelizable fraction > 80%?
    NO  -> Optimize serial code first
    YES -> Fits on one node (128 cores)?
      YES -> Embarrassingly parallel?
        YES -> Use job arrays (simplest!)
        NO  -> Use shared-memory (multiprocessing)
      NO  -> Use MPI (distributed)
Order of preference: Job arrays > Shared memory > MPI
Worked Examples
Parameter Sweep (100 ML trainings, 30s each)
Analysis: Independent tasks, no communication. Use job arrays.
Large Matrix Operations (10,000 x 10,000)
Analysis: Data parallel, fits on one node. Use optimized library (numpy) or multiprocessing.
Benchmarking
PYTHON
import time
from multiprocessing import Pool

for n_cores in [1, 2, 4, 8]:
    start = time.time()
    with Pool(n_cores) as p:
        results = p.map(slow_function, data)
    elapsed = time.time() - start
    speedup = baseline_time / elapsed
    efficiency = speedup / n_cores
    print(f"Cores: {n_cores}, Speedup: {speedup:.2f}x, Efficiency: {efficiency:.1%}")
Look for: speedup increasing with cores, efficiency above 50%, diminishing returns.
Common Mistakes
Mistake 4: Not Checking Correctness
PYTHON
serial_result = [f(x) for x in data]
with Pool(4) as p:
    parallel_result = p.map(f, data)
assert all(s == p for s, p in zip(serial_result, parallel_result))
Challenge
Choose the Right Approach
Problem 1: Process 500 text files (10s each). Total: 83 minutes.
Problem 2: 3D chemical reaction simulation, 1000 time steps, tightly coupled, 2GB memory.
Problem 3: ML parameter search: 20 architectures x 50 hyperparameters x 1000 augmentations = 1M trainings.
Problem 1: Job arrays. Embarrassingly parallel.
sbatch --array=1-500
Problem 2: Shared-memory parallelism. Fits on one
node, but tightly coupled. --cpus-per-task=16
Problem 3: Job arrays with batching. Each job trains
100 models: sbatch --array=1-10000 train_batch.sh. Or
combine with multiprocessing: each job runs 4 trainings in parallel.
Summary
- Measure: Is there a performance problem?
- Profile: Where is the bottleneck?
- Analyze: Is it parallelizable? What fraction?
- Choose: Job arrays > Shared memory > MPI (simplest first)
- Verify: Check speedup and efficiency
- Iterate: Scale up after validating on small test
- Follow a decision framework: measure, profile, analyze, choose, verify
- Job arrays are the simplest approach for embarrassingly parallel problems
- Profile serial code first to identify bottlenecks
- Don’t over-engineer: use the simplest approach that works
- Always validate that parallelization actually improves performance